Nvidia RTX Spark firmware trims Linux inference speed by 35%
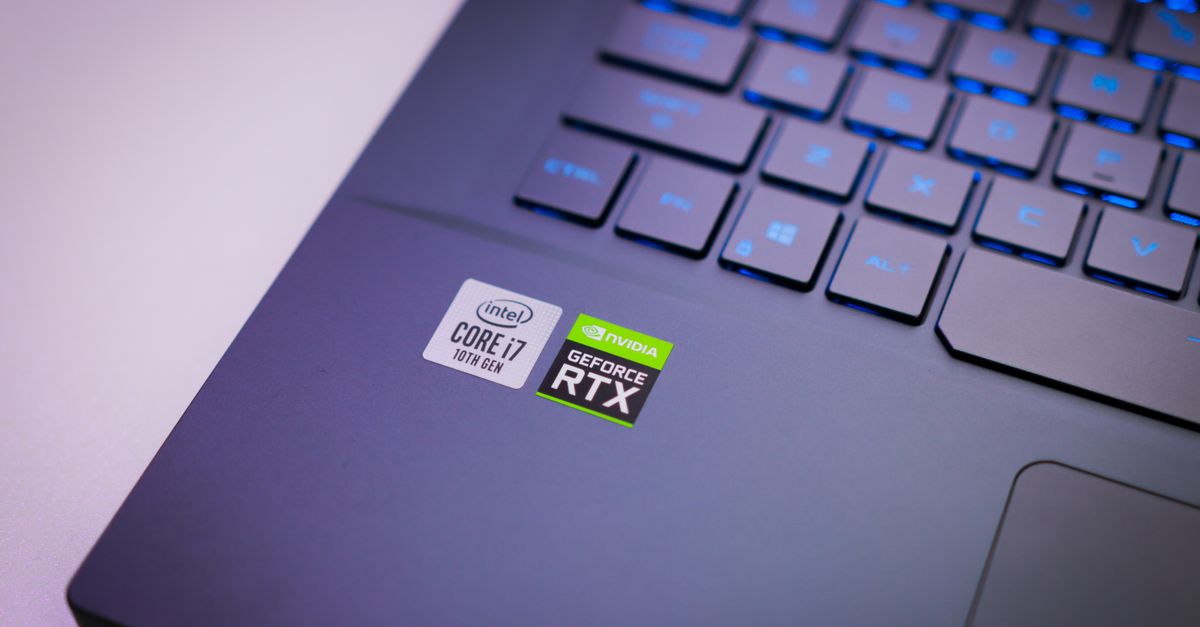
Photo by Foysal Ahmed on Pexels
Encrypted firmware hits inference performance
Nvidia’s RTX Spark firmware now ships encrypted on Linux. MindStudio reports a 35% drop in inference speed for the same model and batch size. The slowdown appears only on Linux; Windows runs the same firmware at expected rates.
The blog post cites a direct comparison on a laptop with an RTX 3070 Ti running a standard LLM benchmark. The Linux run hit 65% of the Windows throughput. The authors attribute the loss to the firmware’s encryption layer, which adds a decryption step to every kernel launch.
Why the penalty matters for developers
AI engineers rely on raw GPU throughput to meet SLAs. A 35% hit can push latency beyond acceptable limits for real‑time chat or recommendation services. The penalty also inflates cloud costs when users rent Nvidia‑accelerated instances.
The issue surfaces just as more teams move inference workloads to on‑prem Linux servers. Enterprises that bought RTX Spark for its claimed performance now face a hidden cost. The slowdown is reproducible across the MindStudio test suite, suggesting it is not an isolated configuration quirk.
Linux driver history and its impact
Nvidia has provided proprietary Linux drivers since 1999. In 2022 the company opened parts of its kernel module under the GPL, simplifying installation on distributions like Arch, Ubuntu and Debian. Users can now pull drivers from official repos and avoid manual blacklist steps for the nouveau driver.
Despite the smoother install path, the driver stack remains closed source for most of the runtime. The encrypted firmware sits on top of that stack, meaning the decryption code cannot be audited or optimized by the community. The lack of transparency fuels suspicion among engineers who prefer open‑source alternatives.
Hybrid graphics and hidden overheads
Many laptops pair an Intel integrated GPU with an Nvidia discrete chip. The Nvidia Prime, suse‑prime and Bumblebee utilities manage the switch. Bumblebee adds a 15‑25 fps penalty in OpenGL workloads because it must copy frames between the discrete and integrated memory buffers.
Hybrid setups also waste power. Logs show discrete GPUs idle at 10‑20 W while integrated graphics draw 2‑4 W. When the discrete GPU is not fully powered down, battery life suffers. The same power‑state management applies to the encrypted firmware: the decryption engine stays active even when the GPU is idle, further draining resources.
Alternatives that avoid Nvidia firmware
The Tara Vision Inference Engine offers a private, OpenAI‑compatible service for Nvidia Linux machines and Apple Silicon Macs. Built on llama.cpp, it runs without telemetry and installs a pinned binary via a single script. The engine fetches its own runtime and does not depend on Nvidia’s encrypted firmware.
Tara Vision’s approach sidesteps the decryption bottleneck. Benchmarks posted by the project show comparable latency to raw Nvidia drivers on the same hardware, but without the 35% hit reported by MindStudio. The service runs as a systemd daemon on Linux, aligning with the same user‑space management model used by Nvidia Prime.
What to watch next
The community will monitor Nvidia’s response to the performance report. Key signals include a firmware update that removes the encryption layer or a driver patch that offloads decryption to a dedicated engine. Developers should also track the adoption rate of third‑party inference services like Tara Vision, which could shift workload patterns away from Nvidia’s proprietary stack.
If Nvidia releases a transparent firmware version, the performance gap may close. Until then, engineers should benchmark both encrypted and unencrypted paths, consider hybrid‑graphics overhead, and evaluate alternative inference stacks before committing to RTX Spark for production workloads.
Related Articles
DeepSeek releases open-source inference engine DeepInfer
DeepSeek puts its DeepInfer inference engine on GitHub, inviting the community to build and optimize large language model serving.
Grok Bot email, Nvidia talks for Reflection AI
Grok Bot can now send email, Nvidia eyes Reflection AI, and a $1.25 billion monthly SpaceX compute contract surfaces, reshaping AI access and infrastructure.
RTX 4090 runs 125B AI model as old AMD cards get Linux boost
A 125‑billion‑parameter model now runs on a consumer RTX 4090, while Valve revives legacy AMD GPUs and industry debates hard budget caps.